Why JAX
Traditional SED (spectral energy distribution) fitting with codes like emcee, Prospector, BAGPIPES, or CIGALE is gradient-free: at every step, the sampler queries the likelihood and proposes the next move. In 10–30 dimensions with 10,000 likelihood calls per chain step, fitting a single galaxy takes hours.
Tengri builds the same physics (stellar populations, dust, nebular emission, active galactic nucleus, intergalactic medium) entirely from JAX primitives, making the model differentiable. The likelihood and its gradient are computed together at no additional cost. Gradient-based samplers (No-U-Turn Sampler, Hamiltonian Monte Carlo, variational inference) then use that gradient to efficiently explore the posterior.
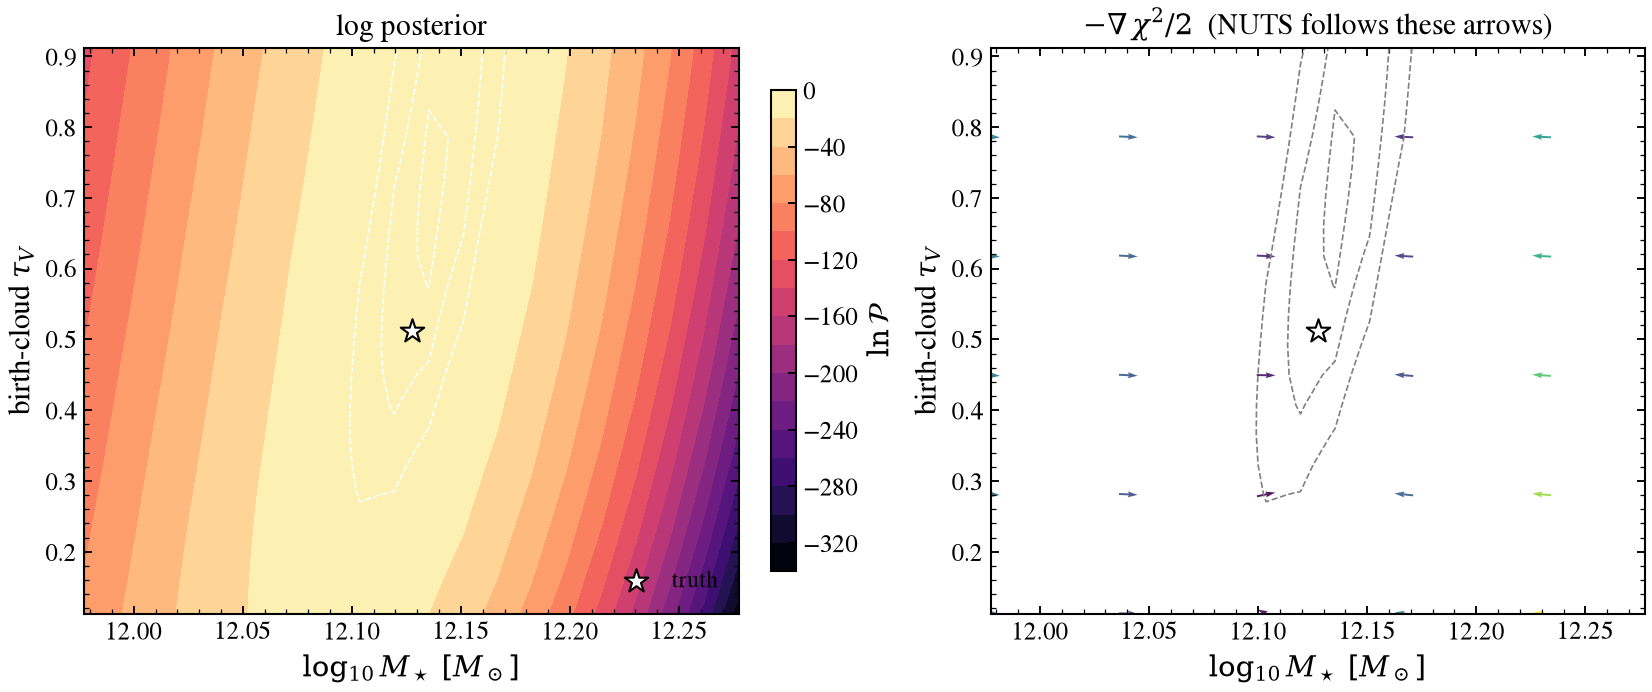
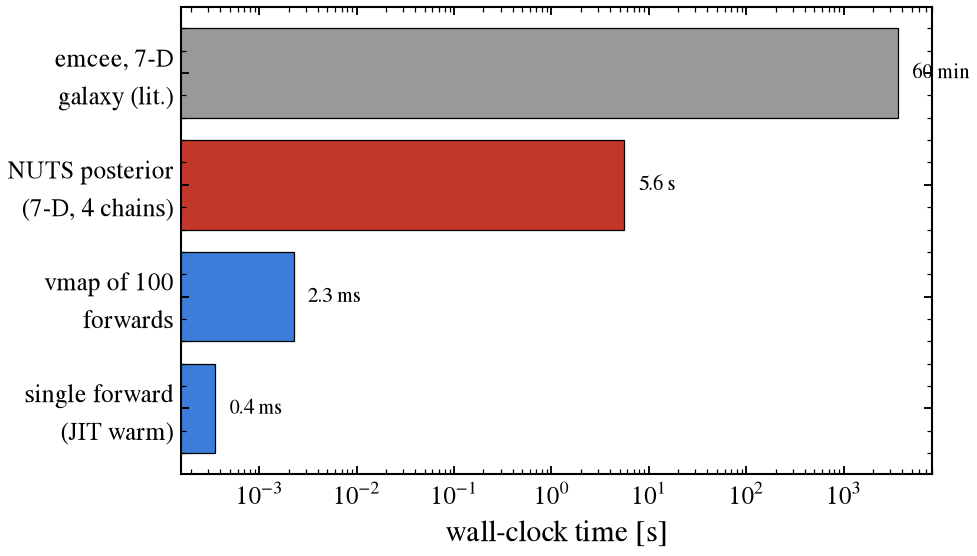
The figures below illustrate this concretely: an astronomer-readable visualization of the posterior gradient, and how that translates into wall-clock time.
[1]:
import os
import warnings

os.environ["TF_CPP_MIN_LOG_LEVEL"] = "2"  # suppress XLA/PjRt C++ INFO+WARNING logs
os.environ["TENGRI_HOST_DEVICES"] = "4"  # enable parallel chain execution on 4 devices

from _setup import quiet

quiet()

# The wNE grid states that its nebular emission is baked in; that is the intent here.
warnings.filterwarnings("ignore", message=".*wNE.*")

# Keep the rendered tutorial clean: silence framework notices that do not
# change the science shown here (baked-in nebular, the WavePrecomp blue-band
# approximation, and recipe/parameter-provenance notices). Genuine
# deprecations in user-facing
# calls are fixed in the code, not hidden.
warnings.filterwarnings("ignore", message=".*BakedInBackend.*")
warnings.filterwarnings("ignore", message=".*WavePrecomp.*")
warnings.filterwarnings("ignore", message=".*states no 'all_params' disposition.*")
warnings.filterwarnings("ignore", message=".*Composable AGN.*")
warnings.filterwarnings("ignore", message=".*before the Big Bang.*")
warnings.filterwarnings("ignore", category=RuntimeWarning)

from pathlib import Path
from time import perf_counter

import jax
import jax.numpy as jnp
import matplotlib.pyplot as plt
import numpy as np

from _setup import FIG_DIR
import tengri
from tengri import (
    ForwardModel,
    Observation,
    Photometry,
    SEDModel,
    generate_mock,
    plot,
    recipes,
)

plot.setup_style()
A minimal star-forming galaxy
recipes.mock_recovery_minimal() is the lightest stable model: a truncated-skew-normal SFH, single dust optical depth, and baked-in nebular emission. Seven free parameters yield inference in seconds.
[2]:
SSP_NAME = "prsc_miles_chabrier_wNE"
ssp = tengri.load_ssp(SSP_NAME, download=True)

obs = Observation(
    photometry=Photometry.from_names(["sdss_u", "sdss_g", "sdss_r", "sdss_i", "sdss_z", "wise_w1"])
)
cfg = {**recipes.mock_recovery_minimal(), "neb": {"type": "ssp"}}  # the wNE grid carries its nebular emission; the recipe's "no nebular" entry is replaced
model = SEDModel.build(ssp_data=ssp, observation=obs, **cfg)

truth = model.spec.sample(jax.random.PRNGKey(0))
mock = generate_mock(model, truth, key=jax.random.PRNGKey(1), snr=20.0)
flux_obs, noise = mock["flux_obs"], mock["noise"]
Figure 1: the posterior gradient
Two free parameters are varied on a 20×20 grid with the rest fixed at the truth: the total stellar mass formed and the birth-cloud optical depth. The left panel shows the log-posterior surface with contours at 1σ / 2σ / 3σ significance. The right panel shows jax.grad of the same quantity, plotted as a vector field.
A gradient-free sampler explores by trial-and-error, while a gradient-based sampler reads the arrows. In one or two dozen dimensions, that is the difference between hours and seconds.
[3]:
base = dict(truth)
free_keys = ("sfh_tsnorm_log_total_mass", "dust_tau_bc")

m0 = float(truth[free_keys[0]])
t0 = float(truth[free_keys[1]])
log_m_grid = np.linspace(m0 - 0.15, m0 + 0.15, 20)
tau_grid = np.linspace(max(0.0, t0 - 0.4), t0 + 0.4, 20)
LOGM, TAU = np.meshgrid(log_m_grid, tau_grid, indexing="ij")


def neg_log_post(log_m, tau):
    p = dict(base)
    p[free_keys[0]] = log_m
    p[free_keys[1]] = tau
    flux_pred = model.predict_photometry(p)  # canonical lean JIT/vmap-safe path
    chi2 = jnp.sum(((flux_pred - flux_obs) / noise) ** 2)
    return 0.5 * chi2  # uniform priors → χ²/2 = -ln posterior up to const


# Sequentialize: call scalar functions in a loop, each JIT-compiled to its own kernel. Vmapping over the grid would trace the entire orchestrator state pytree (n_age × n_wave × n_grid), exhausting memory; scalar calls reuse the same kernel and stay well under a gigabyte.
neg_log_post_jit = jax.jit(neg_log_post)
grad_jit = jax.jit(jax.grad(neg_log_post, argnums=(0, 1)))

nll_grid = np.zeros_like(LOGM)
g_log_m = np.zeros_like(LOGM)
g_tau = np.zeros_like(LOGM)
for i in range(LOGM.shape[0]):
    for j in range(LOGM.shape[1]):
        nll_grid[i, j] = float(neg_log_post_jit(LOGM[i, j], TAU[i, j]))
        gx, gy = grad_jit(LOGM[i, j], TAU[i, j])
        g_log_m[i, j] = float(gx)
        g_tau[i, j] = float(gy)

log_post = -(nll_grid - nll_grid.min())  # peak at zero
step_x, step_y = -g_log_m, -g_tau  # ascend the posterior
mag = np.hypot(step_x, step_y)
step_x = step_x / (mag + 1e-12)
step_y = step_y / (mag + 1e-12)

fig, axes = plt.subplots(1, 2, figsize=(11, 4.6), constrained_layout=True)
levels = -np.array([0.5 * s * s for s in (1.0, 2.0, 3.0)])[::-1]
cs = axes[0].contourf(LOGM, TAU, log_post, levels=20, cmap="magma")
axes[0].contour(LOGM, TAU, log_post, levels=levels, colors="white", linewidths=0.8)
axes[0].scatter(
    [truth[free_keys[0]]],
    [truth[free_keys[1]]],
    marker="*",
    s=140,
    c="white",
    edgecolor="k",
    zorder=5,
    label="truth",
)
axes[0].set_xlabel(r"$\log_{10} M_\star\ [M_\odot]$")
axes[0].set_ylabel(r"birth-cloud $\tau_V$")
axes[0].set_title("log posterior")
axes[0].legend(loc="lower right", frameon=False)
fig.colorbar(cs, ax=axes[0], shrink=0.85, label=r"$\ln \mathcal{P}$")

stride = 4
axes[1].contour(LOGM, TAU, log_post, levels=levels, colors="0.5", linewidths=0.8)
axes[1].quiver(
    LOGM[::stride, ::stride],
    TAU[::stride, ::stride],
    step_x[::stride, ::stride],
    step_y[::stride, ::stride],
    mag[::stride, ::stride],
    cmap="viridis",
    pivot="middle",
    scale=35,
    width=0.003,
    alpha=0.9,
)
axes[1].scatter(
    [truth[free_keys[0]]],
    [truth[free_keys[1]]],
    marker="*",
    s=140,
    c="white",
    edgecolor="k",
    zorder=5,
)
axes[1].set_xlabel(r"$\log_{10} M_\star\ [M_\odot]$")
axes[1].set_ylabel(r"birth-cloud $\tau_V$")
axes[1].set_title(r"$-\nabla\, \chi^2 / 2$  (NUTS follows these arrows)")
fig.savefig(FIG_DIR / "01_gradient_map.png", dpi=300, bbox_inches="tight")
Three lines of code carry that whole picture:
[4]:
def loss(p):
    return 0.5 * jnp.sum(((model.predict_photometry(p) - flux_obs) / noise) ** 2)


grad_at_truth = jax.grad(loss)(truth)
{k: float(v) for k, v in grad_at_truth.items() if k in free_keys}
[4]:
{'dust_tau_bc': -8.578857440601778,
 'sfh_tsnorm_log_total_mass': 14.396054179959329}
Figure 2: forward-model throughput
A single forward call is compared with vmap over 100 parameter draws. The batched call is far below 100 times the single-call cost. This scaling enables gradient samplers, population fits, and posterior-predictive sweeps to run on a laptop.
[5]:
# Trigger the first JIT compile on a single call (cold cache).
_ = model.predict_photometry(truth).block_until_ready()

t0 = perf_counter()
for _ in range(50):
    # Warm cache: all 50 calls reuse the same compiled kernel.
    _ = model.predict_photometry(truth).block_until_ready()
t_single = (perf_counter() - t0) / 50

tengri.clear_shared_caches()  # free graphs from the gradient figure
n_batch = 100
keys = jax.random.split(jax.random.PRNGKey(5), n_batch)
batch_params = jax.vmap(model.spec.sample)(keys)
forward = jax.jit(jax.vmap(lambda p: model.predict_photometry(p)))

_ = forward(batch_params).block_until_ready()  # cold-compile: triggers JIT trace+compile
t0 = perf_counter()
_ = forward(batch_params).block_until_ready()
t_batch = perf_counter() - t0

t0 = perf_counter()
# The default fit: four NUTS chains on the mass-profiled posterior with a dense metric. Seven parameters matches the emcee comparison dimensionality for fair comparison.
fwd_model = ForwardModel.build(sed=model)
posterior = fwd_model.fit(flux_obs, noise, key=jax.random.PRNGKey(2), verbose=False)
t_nuts = perf_counter() - t0

print(f"NUTS posterior, 4 chains x 300 draws: {t_nuts:.1f} s")

bars = {
    "single forward\n(JIT warm)": t_single,
    f"vmap of {n_batch}\nforwards": t_batch,
    "NUTS posterior\n(7-D, 4 chains)": t_nuts,
    "emcee, 7-D\ngalaxy (lit.)": 3600.0,
}
fig2, ax = plt.subplots(figsize=(6.8, 4.0))
colors = ["#3b7dd8", "#3b7dd8", "#c3372a", "0.6"]
ax.barh(list(bars), list(bars.values()), color=colors, edgecolor="k", linewidth=0.6)
ax.set_xscale("log")
ax.set_xlabel("wall-clock time [s]")
for i, v in enumerate(bars.values()):
    if v < 1.0:
        label = f"{v * 1e3:.1f} ms"
    elif v < 120:
        label = f"{v:.1f} s"
    else:
        label = f"{v / 60:.0f} min"
    ax.text(v * 1.4, i, label, va="center", fontsize=10)
fig2.tight_layout()
fig2.savefig(FIG_DIR / "01_wallclock.png", dpi=300, bbox_inches="tight")
NUTS posterior, 4 chains x 300 draws: 5.6 s
Two switches worth knowing
``compile=`` controls how the forward model is JIT-wrapped at build time. per_component (the default) compiles each SEDComponent independently, giving fast cold start and friendliness to notebook iteration. fused compiles the full pipeline as one graph, slower on first call but fastest in steady state, which is what a population fit needs.
[6]:
cfg = {**recipes.mock_recovery_minimal(), "neb": {"type": "ssp"}}  # the wNE grid carries its nebular emission; the recipe's "no nebular" entry is replaced
model_fused = SEDModel.build(
    ssp_data=ssp,
    observation=obs,
    compile="fused",
    **cfg,
)
Persistent JAX cache. Importing tengri enables an on-disk JIT cache at ~/.cache/tengri_jax_cache. Kernel restarts and new Slurm worker launches do not trigger recompilation of unchanged components; the first forward pass of a fresh process is already warm. Cache management has four modes: tengri.lean (default, drops the engine after each fit), tengri.persistent (keeps it for repeated same-shape fits), tengri.gc (one-shot garbage collection), and
tengri.clear_shared_caches() (full reset for clean benchmarking).
What this enables
Population fits across thousands of galaxies become tractable on a laptop rather than a cluster. Hierarchical priors, where each galaxy’s posterior informs a shared parent distribution, are sampled jointly instead of post-hoc. High-dimensional non-parametric SFHs (30 or more bins) are sampled in minutes. The next notebooks build the model component by component.